


Ask most revenue teams to describe their ICP and they’ll give you an answer sounding something like ‘B2B SaaS, 50 to 500 employees, headquartered in the US or UK, Series A and above’. Maybe a vertical or two if they’re feeling specific.
But that ICP likely matches the description used by half the businesses in America - when your ICP should be the most unique thing about your business.
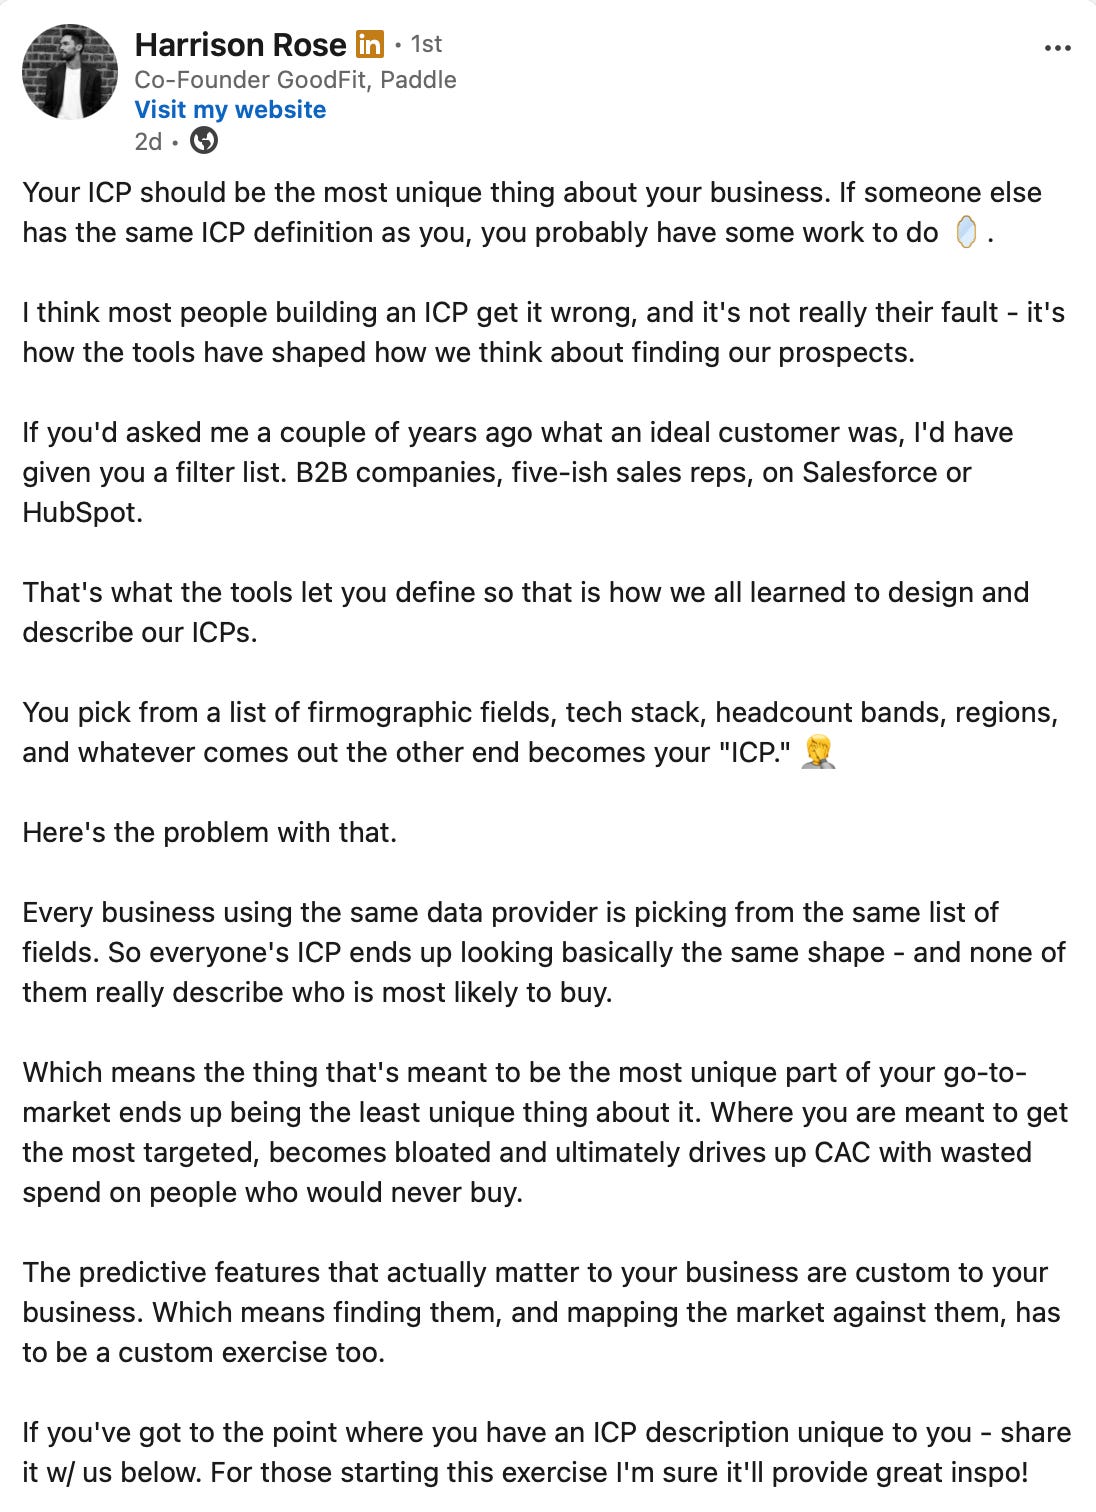
ICP’s like this are not unusual, defined at some point in a strategy session, based on available filters in a traditional data providers drop down, then written down in a deck or a doc that everyone signed off on, and then work continued.
But these kinds of ICPs need to be re-tested, using the data and technology we have access to today - in an exercise to stress test your definition genuinely separates who is a good buyer from who isn’t - or identify what does.
An ICP audit allows you to test whether your stated qualification criteria actually separate qualified accounts from disqualified ones - using a list of accounts you’d sell to and a list you know are unqualified.
The problem is that most ICP definitions aren’t full enough. They attempt to describe the companies that have bought from you, or the companies that look like the companies that have bought from you. But they don’t explain why those companies bought, what made them structurally qualified in ways that others weren’t, or whether the pattern is still true today.
They’re further diluted when translated into the available filters when building lists of accounts, as they are limited to company location, headcount and industry. And so revenue teams run campaigns against a patchy definition and are never truly stress-tested.
Then it’s a mystery why win rates are inconsistent, why some accounts convert quickly and others stall, and why execution feels harder than it should.
The answer, more often than not, is that they’re pointing their execution at the wrong target. This playbook walks you through how to find the right one.
Key takeaways from this playbook
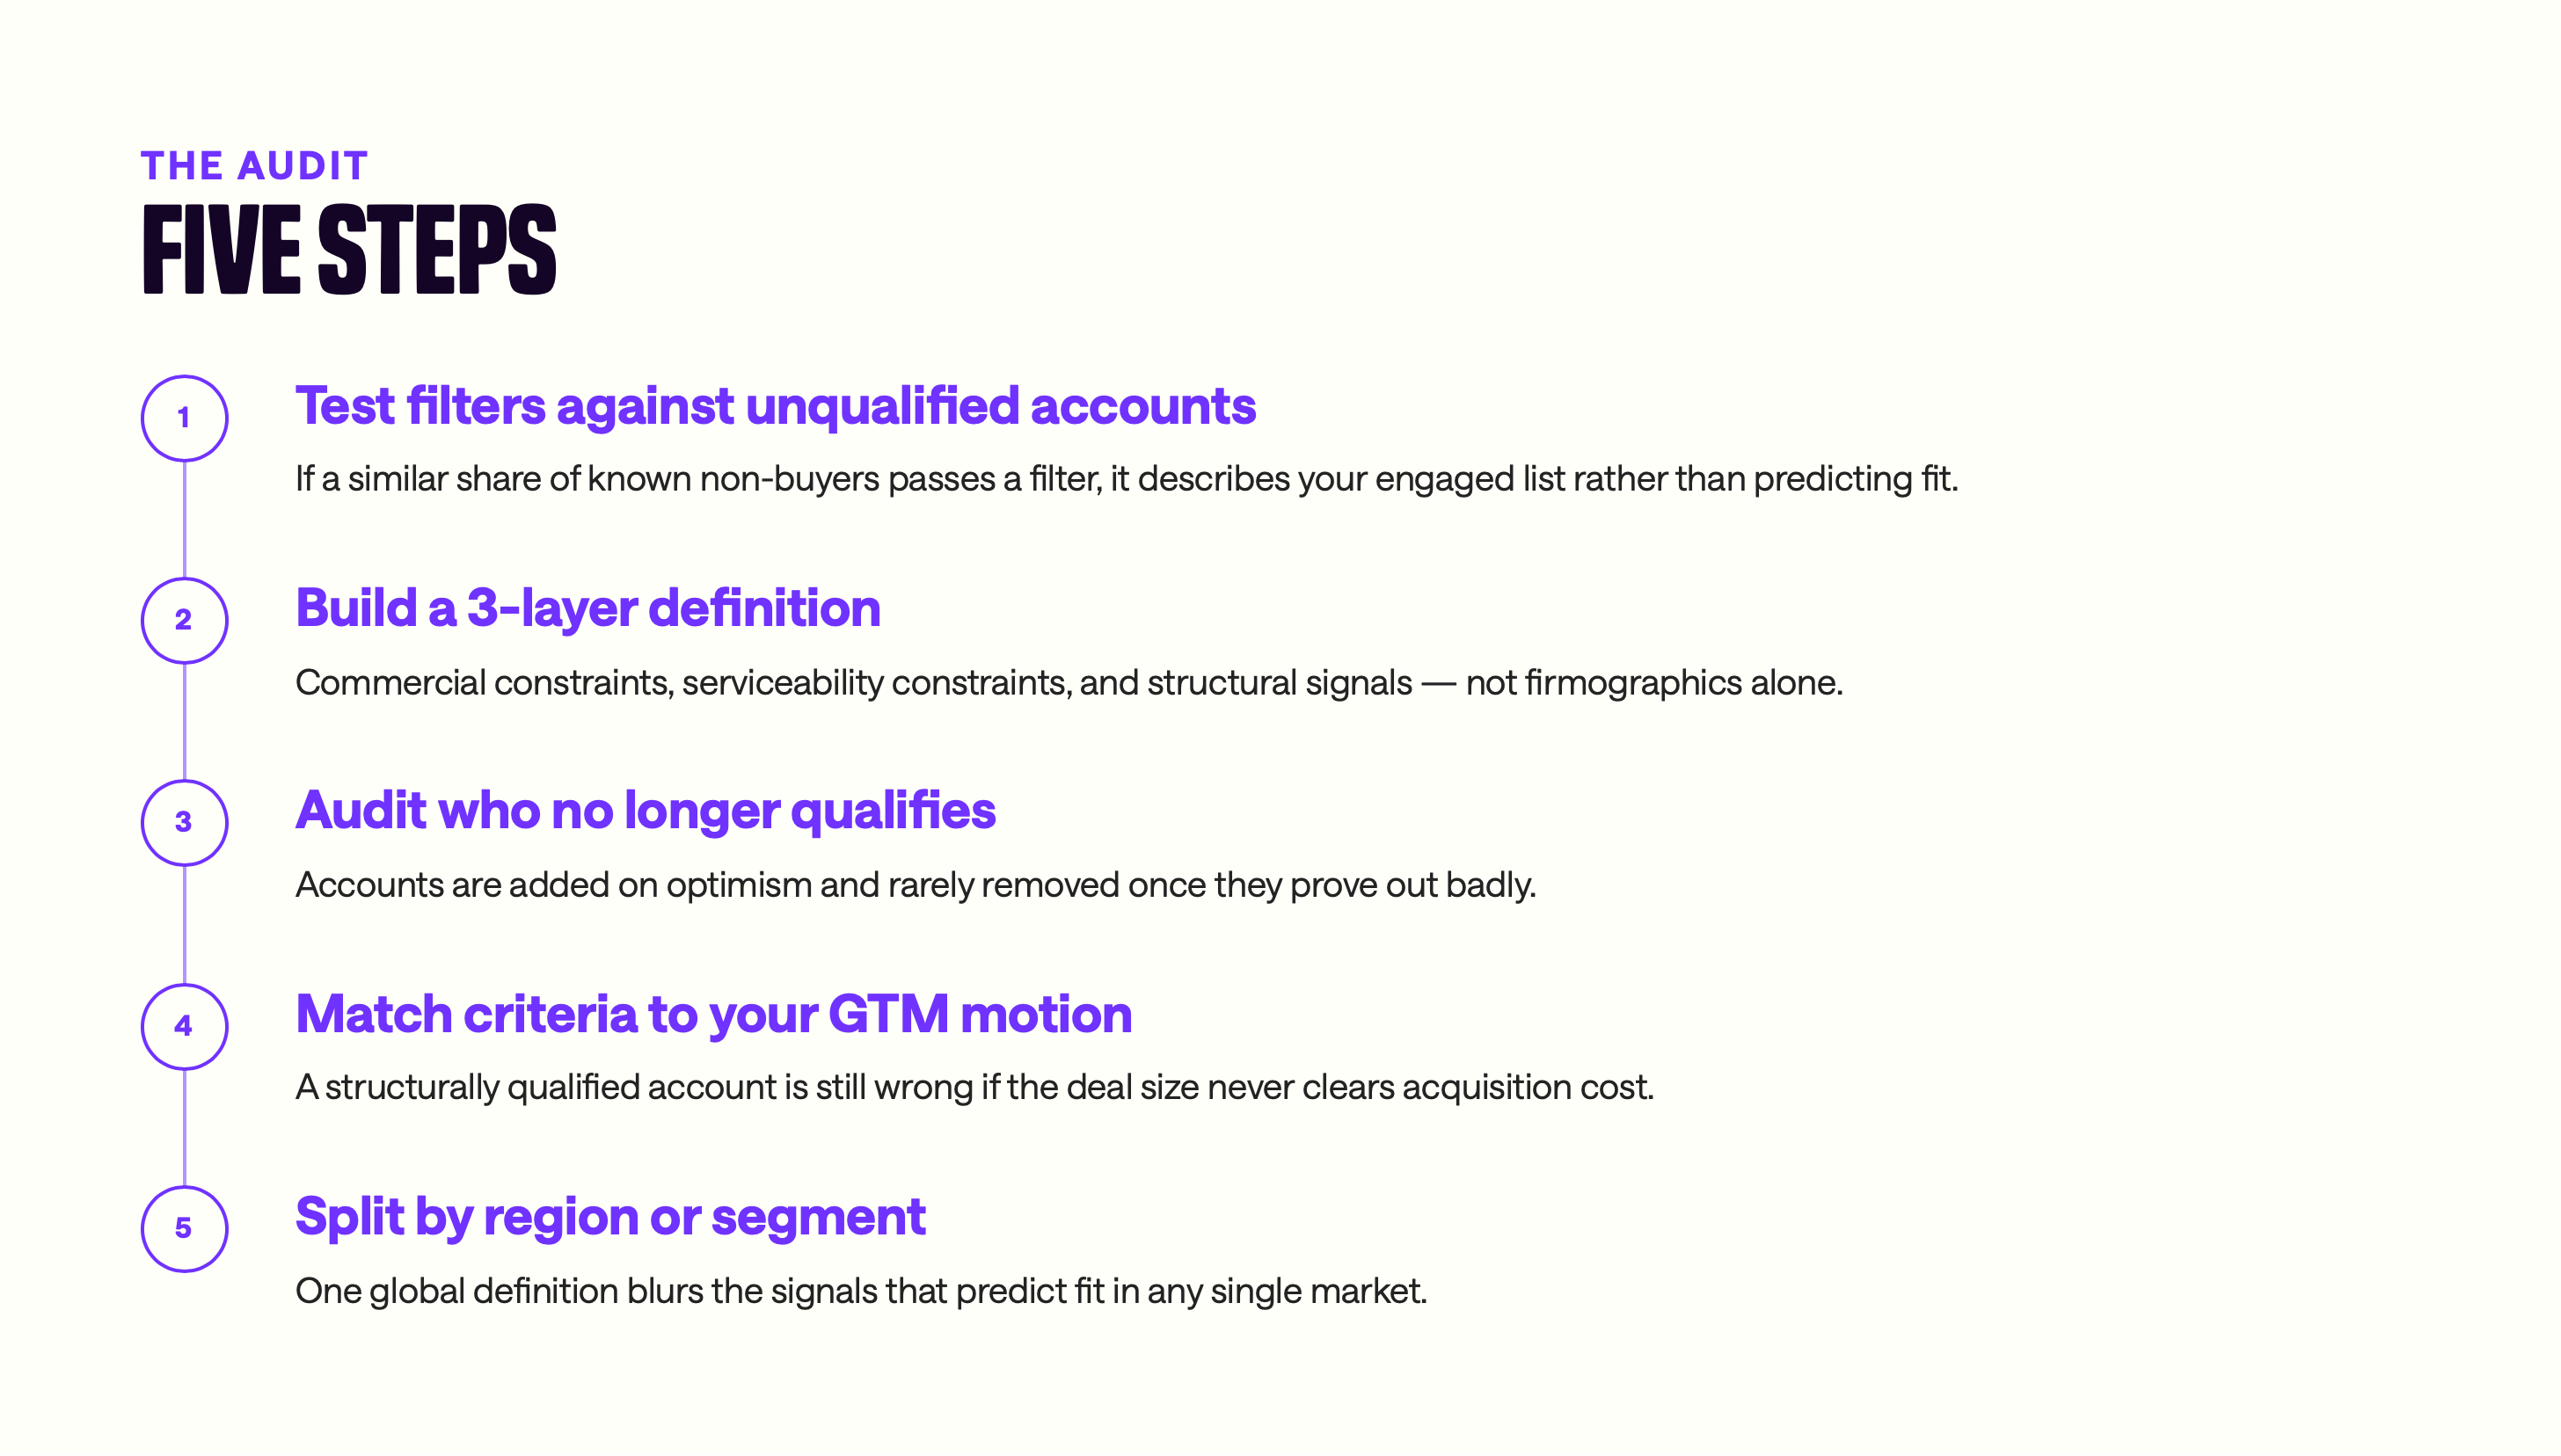
A qualified account isn’t just one that fits your industry and headcount filters - it’s one you can afford to win, can actually serve, and structurally needs what you sell. Here’s the 5-step audit:
Test your filters against disqualified accounts. If a similar share of your disqualified accounts would pass the same criteria as your qualified list, that filter is describing who you’ve engaged with, not predicting fit.
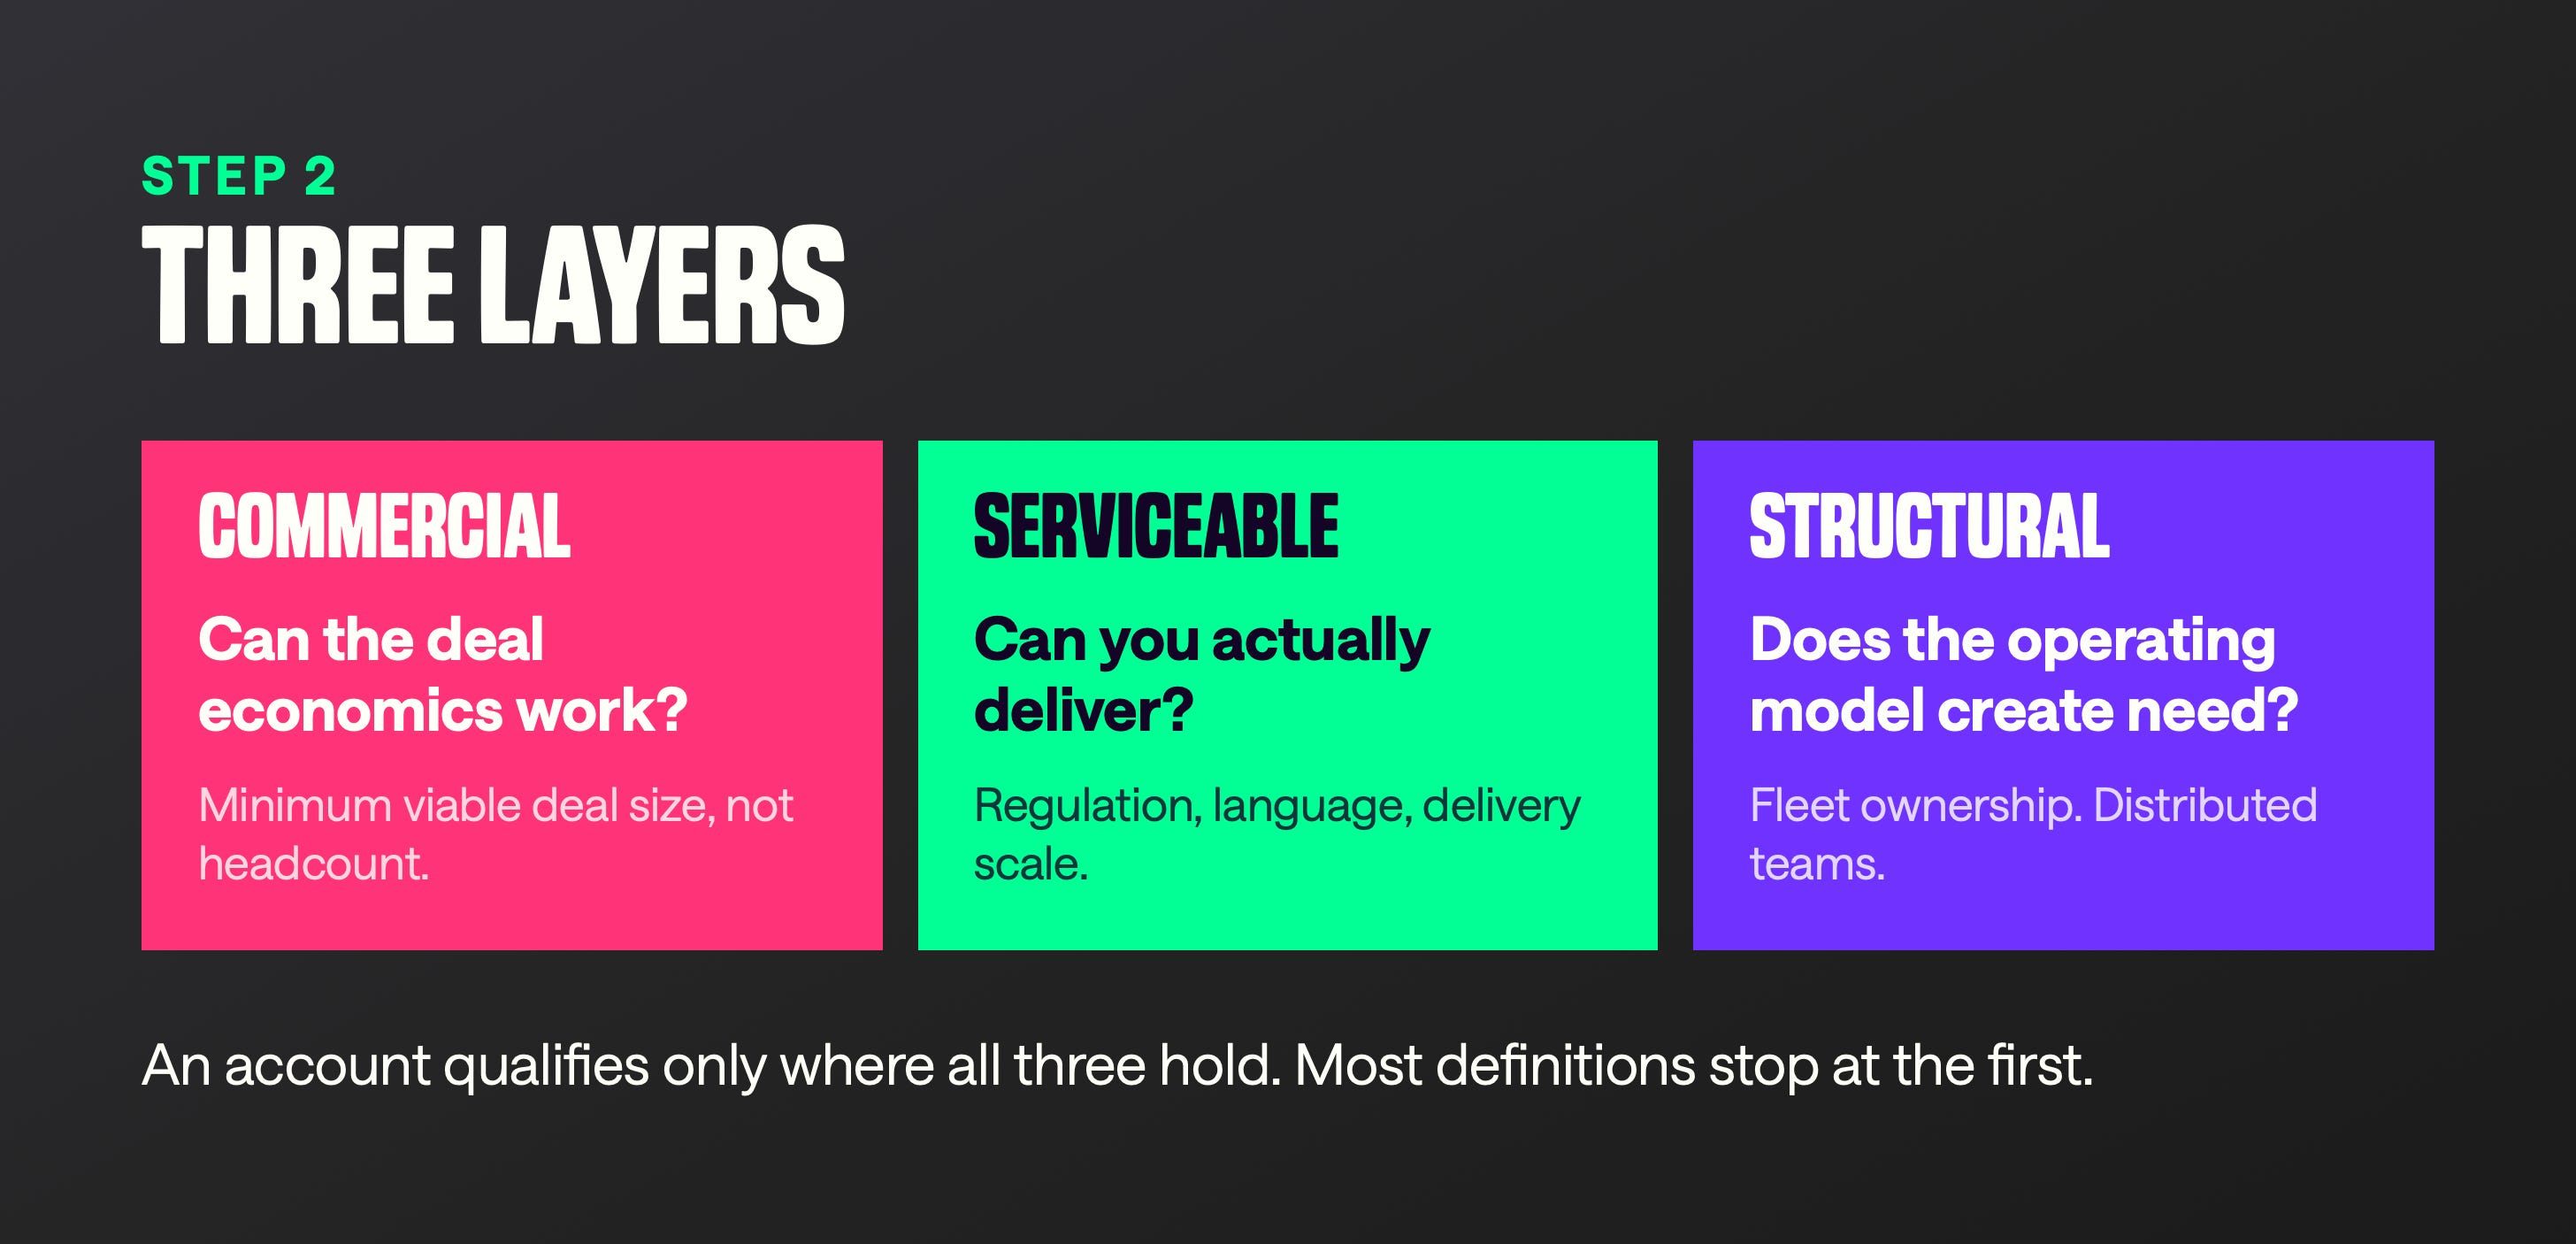
Build a 3-layer definition. Commercial constraints (can the deal economics work), serviceability constraints (can you actually deliver), and structural signals (does the account’s internal setup create real need) — most teams only ever build the first.
Audit who no longer qualifies. Accounts get added to a target list on optimism and rarely get removed once they prove out badly; check what’s sitting in your CRM that shouldn’t still be there.
Match your criteria to your GTM motion. A structurally qualified account can still be the wrong account if the deal size doesn’t clear your acquisition cost or your motion can’t execute at that scale.
Split your definition by region or segment. A single global ICP tends to blur the signals that actually predict fit in any one market - separate definitions usually sharpen accuracy in both.
Before and after: two examples of a rebuilt ICP
It’s easier to see why a layered definition outperforms a firmographic one when you compare the two versions side by side.
Before: A project management tool defines its ICP as “B2B companies, 50 to 250 employees, US-based, Series A or above.”
After: Having gone through the audit, they discover that headcount and funding stage explain almost nothing about who renews. What it does explain is whether the company runs distributed teams across multiple time zones, since that’s the operating model that makes asynchronous project tracking a necessity rather than a nice-to-have.
Deal economics rule out anything below a certain seat count, since the sales cycle cost doesn’t clear at smaller volumes. And serviceability rules out companies without a US-based decision-maker, since the support model can’t currently stretch further.
The revised definition says ‘a distributed, multi-timezone team, a minimum seat threshold, and a US-based buyer, with headcount and funding stage dropped as hard filters and kept only as loose context.’
Here is another example.
Before: A vertical SaaS company selling into logistics defines its ICP as “logistics and supply chain companies, mid-market, North America.”
After: Having applied the audit, it reveals that “logistics” was doing no filtering at all - the qualified and unqualified account lists were nearly identical once industry was the only lens. The real divide was whether a company managed its own fleet versus outsourcing transport entirely, because only the former had the operational pain the product addressed.
Structural signals included fleet ownership, checkable through DOT registration data and job postings for dispatch or fleet roles. The revised definition narrows from an entire industry to a specific operating model within it.
In both of these examples, what leadership thought was a well defined ICP didn’t have any real lifting power.
3 signs your ICP definition is outdated or unreliable
Most teams skip the audit because they believe they’ve already done it. But if you’re reading this - you’re maybe already questioning whether you need to dig deeper…
So here are some questions to ask yourself to help identify if you need to redefine your ICP.
1. Is it written down?
And by written down, meaning somewhere that a new hire could find it, read it, and use it to make a targeting decision without asking someone else.
If the answer is no - or ‘sort of’ - your ICP is at risk of drift.
2. Does everyone agree?
Ask your Head of Sales, your Head of Marketing, and your most experienced AE to each write down the top five attributes of your ideal customer, then compare the answers.
If they differ significantly, then they have each interpreted the vague ICP differently based on their ‘jobs to be done’, meaning qualification criteria shift depending on who’s doing the qualifying, and targeting decisions get made based on whoever has the most air time in the room.
3. When was it last updated?
An ICP built on last year’s closed-won data is a hypothesis about this year’s market.
Especially considering the rate at which markets are evolving with tech advances, product releases and with those, the needs of buyers. The segments that drove early growth are not necessarily the segments that warrant the most attention today.
Your ICP should be a living, breathing entity that updates as often as possible to keep accurate.
How to audit your ICP in 5 steps
Step 1: Test your ICP filters against unqualified accounts, not just qualified ones
Your ICP definition is almost certainly built on firmographic filters, meaning industry, company size, geography, and perhaps funding stage. These are the easiest attributes to apply at scale, which is why they dominate, but they’re certainly not the most predictive.
The first step of a real audit is to put each of your current filters to a single test - does this filter predict qualification, or just describe your qualified account list?
A filter that describes qualification looks at your qualified account list, notices that most of them are in the 200 to 500 employee band, and codes that as a signal. A filter that predicts qualification can tell you, before you’ve engaged with an account - whether structural fit is likely to exist.
A competitive-intelligence software company ran the filter audit for real. Their ICP had been built from instinct, refined only by who’d already bought, and it had never been tested against a list of companies known not to be buyers.
They pulled a full list of qualified accounts alongside a list of accounts confirmed as unqualified, enriched both with a deep set of company-level attributes, and re-ran their stated criteria against both sets. The exercise didn’t just validate or kill individual filters - it became the basis for an entirely rebuilt ICP, which they then operationalised directly into outbound prioritisation and market mapping.
The diagnostic question is ‘what do our qualified accounts have in common that known non-buyers don’t’.
The revised approach drops any filter that fails the test as a hard qualifier and keeps it, if at all, as loose context rather than a gate. The target list shrinks to only the accounts where the surviving filters genuinely separate wins from losses.
Running this test properly - across a full multi-year window, filter by filter - is where most teams stall out because doing it by hand across hundreds of accounts and dozens of candidate filters is slow enough that most teams end up testing whichever variable is loudest instead.
The mechanism underneath a proper filter audit is always the same, whether a person is running it manually or it’s built to run continuously. Form a hypothesis about what separates buyers from non-buyers, test that hypothesis against a real list of qualified and unqualified accounts rather than a sample, then keep testing combinations until you find the set that actually predicts fit rather than just describing it after the fact.
This is the process Goodfit’s model runs at scale - one proposes the qualifying criteria, a second checks each account against real data to see where the hypothesis holds and where it breaks, and a third tests combinations until the criteria set actually separates your qualified accounts from your unqualified ones. Meaning thousands of combinations can be run in a much shorter timeframe.
How to test whether an ICP filter is predictive
For each of your existing filters, calculate two things.
What percentage of your qualified accounts (accounts you’d sell to, not just existing customers) would pass this filter.
What percentage of your unqualified accounts (known non-buyers) would also pass it.
If a filter lets through most of your qualified accounts and most of your unqualified ones, it isn’t doing any work.
A quick note on what belongs in “known non-buyers”. Accounts that lost because they were never structurally qualified - wrong operating model, no real need, deal economics that never worked. Accounts that lost for reasons unrelated to fit, for example timing, a stalled champion, a rep who dropped the ball - shouldn’t be counted as unqualified. They’re unresolved and including them will train your filters on the wrong signals.
Common findings at this stage:
Industry is weaker than assumed. Teams often discover that an industry they’d excluded was never actually tested against the data - and may have been filtering out accounts that belonged in the market all along.
Headcount doesn’t hold universally. For businesses that sell to agencies, channel partners, or companies with app-driven revenue models, employee count is a particularly unreliable proxy. A small agency reselling data to large end-clients can be a significantly better customer than a 300-person company in the “right” band.
Technographic signals carry history. A tool in a prospect’s stack tells you something about the kind of company they are, but whether that’s a good sign or a bad one depends entirely on your own ICP, and can flip without warning. Spotting a basic, free-tier marketing tool might once have flagged a company as too small to bother with - if the business has since moved into serving exactly that segment, the same signal now marks a good-fit account. Treating any tool as a permanent positive or negative, without checking that the read still matches who you’re selling to today, risks classifying accounts in the wrong direction permanently.
The goal of this step is not to arrive at a final, revised filter set. It’s to create an honest inventory of which of your current criteria are doing real work, and which are assumptions you haven’t examined.
Step 2: Build a 3-layer ICP - commercial, serviceability, and structural
Firmographic filters - industry, headcount, geography - are the starting point. They are necessary but not usually sufficient. A real ICP definition operates across at least three distinct layers. Most teams have only ever built one.
Layer 1: Commercial constraints (minimum deal size and economics)
Commercial constraints are the economic conditions that make an account worth pursuing, not whether they’d benefit from the product, but whether the deal economics make sense.
These constraints are almost never explicitly stated in an ICP definition, even though they eliminate a significant portion of any filtered list. The accounts that look right on paper but will never reach your minimum deal size are not qualified accounts.
The exercise here is to define, with specificity, the commercial floor that makes an account worth engaging:
What is your minimum viable deal size, and what account attributes predict it? Revenue, spend levels in adjacent categories, team size in the function you’re selling to - these are more direct indicators than company headcount.
Is there a minimum scale threshold below which the problem you solve doesn’t exist, or exists but isn’t painful enough? For some products, the pain only materialises at a certain volume.
Are there account types that look right by size but generate poor deal economics? Short sales cycles on small deals, or long cycles on deals that are likely to churn? These are ICP mismatches.
One ad-spend protection platform went through this exercise and discovered that their real qualification threshold was a minimum monthly ad spend level that made their product economically meaningful, which was not reflected anywhere in their ICP definition.
They had been pursuing accounts that looked right and were in the right sector, but would never generate a viable deal. The commercial constraint was implied internally but it was never codified into the definition.
A separate company, an MSP-tooling vendor, found their real commercial floor wasn’t headcount or revenue band but operational depth. An MSP servicing roughly 20+ end customers, translating to about £12k in annual spend.
Below that, even a structurally correct, willing buyer was, in their words, “often not profitable to pursue.” The threshold had existed informally inside the team for a while, the audit just forced it into the written definition and formally excluded who didn’t fit.
Layer 2: Serviceability constraints (geography, language, delivery capacity)
Serviceability constraints are the structural limitations on which accounts you can actually serve well. These constraints are frequently invisible in ICP definitions because they feel like delivery problems rather than qualification problems. But an account that can’t be properly served isn’t truly qualified, even if it looks that way on paper - closing it just trades pipeline for churn risk.
Common serviceability constraints that belong in your ICP definition:
Geographic and regulatory limitations. If your product is constrained by regulatory frameworks - data residency, financial compliance, sector licensing - then a company operating primarily outside your serviceable region doesn’t qualify, regardless of how well they fit every other criterion.
For one business, geography became a hard qualification factor not out of GTM preference but KYC constraint - certain markets simply couldn’t be served, regardless of fit.
Language and market coverage gaps. If you have no German-speaking support, a German-headquartered company with German-language workflows is underqualified because of your current ability to serve them.
Minimum scale for delivery. For some businesses, the product only generates meaningful ROI above a certain operational scale.
For another, the minimum had nothing to do with company size at all - it was a minimum number of partner accounts that made the platform economics work, with delivery risk below that threshold making the deal a poor bet regardless of willingness to buy.
Layer 3: Structural and operational signals (how a company actually operates)
This is the layer that most ICP definitions are missing entirely, and it’s the one that does the most predictive work.
Structural and operational signals are attributes of how a company is built and how it operates. They answer the question ‘does this company have the internal conditions that make our product solve a real problem?’ These signals vary significantly by product and market.
A web-scraping and data-infrastructure company found that firmographic filters told them almost nothing about fit. The real qualifier was structural. Scraper activity, a genuine data-engineering function, and active hiring in that area, together. Any one or two of those signals on their own weren’t reliable. It was the combination that predicted real pain.
The harder problem, in their own words, was that even layered on top of a data provider, they “struggle to reliably get or triangulate this data” - they knew what predicted fit, they just couldn’t find it at scale.
The common thread with structural signals generally is that they’re rarely the thing a firmographic ICP definition already captures. They have to be derived from how a company actually operates - job postings, team composition, tooling, hiring patterns - not pulled from a standard data provider’s existing fields.
How to find your structural signals
This is where the work gets harder, because structural signals surface from analysing your wins.
Take your last twenty customers and examine them not just for what they have in common in terms of size and sector, but for what they have in common in terms of how they operate.
What did they all have going on internally that made your product solve a real problem? What was true of each of them that wasn’t true of similarly-sized accounts you know are unqualified?
This is much easier said than done, because you need access to vast amounts of data to do the analysis properly (which is where Goodfit’s model comes in), but the answer to that question is your structural signal.
Once you’ve identified it, the next challenge is finding an observable attribute that predicts its presence, because you can’t run a GTM motion on criteria you can’t identify at scale.
Why structural signals are now identifiable at scale
For most of the last decade, the structural signals described above were real but practically unusable. You could theorise that a genuine data-engineering function with active hiring in that area, or fleet ownership, predicted fit, but there was no way to check that theory against an entire market without a research team doing it by hand, one job posting and team page at a time.
That’s the constraint that’s changed. Reasoning at this depth, reading job postings, team structures, tenure patterns, tech stack composition, and classifying what they imply, can now be done at the scale of a whole market rather than a sample of twenty accounts using AI with human-level reasoning.
Step 3: Audit which accounts in your CRM no longer qualify
Most ICP audits focus entirely on qualification, meaning who should be in the market. But it’s important not to disregard the second and often more revealing exercise, disqualification. Meaning who is currently in your CRM, or in your target lists, that definitively shouldn’t be.
When we take an average from our experiences mapping our customers’ markets, we found that on average, 70% of the accounts in their CRMs were outside of their real market.
ICP definitions are typically additive. Accounts get added when someone thinks they might be a fit, and they tend to rarely get removed when evidence suggests they’re no longer a fit. The result, in most CRMs, is an accumulation of accounts that were optimistic additions at some point and have never been examined since.
The disqualification audit is not about pruning for its own sake. It’s about understanding whether your current definition is doing the job it’s supposed to do.
The questions to ask:
What accounts in your CRM have been marked as ICP-fit but never engaged meaningfully? What do they have in common?
What accounts have churned, and what were the attributes that should have predicted the churn? Were those attributes in your ICP criteria?
What accounts have long sales cycles and low close rates despite appearing to fit your ICP? What’s actually different about them?
What does your closed-lost data look like by disqualification reason? Are there patterns in the attributes of accounts that consistently reach a certain stage and then stall?
A marketing-analytics company found the inverse problem. Their team had assumed accounts tagged non-ICP weren’t worth sales time, and never revisited that tag as deals actually closed.
When they checked, 61% of their current deals were sitting in accounts marked non-ICP. The tagging had calcified - nothing in their process ever triggered someone to go back and re-examine a designation once it was set.
Which meant that their ICP definition was expanding with no mechanism to contract it. The result was a target list that was nominally qualified but operationally unusable.
Running this audit by hand across a full CRM is exactly the kind of thing that never gets done (this, too, is where Goodfit comes in), but the diagnostic questions above are worth asking regardless of who’s checking the answers.
Step 4: Match your ICP to your GTM motion and deal economics
Your qualification criteria need to be compatible with your go-to-market motion, not just with your product.
Minimum viable scale for your motion
Some accounts are structurally qualified for your product but require a sales motion that you’re not currently set up to execute. Enterprise accounts with long procurement cycles, complex security and legal reviews, and multiple buying stakeholders are a different motion from mid-market accounts with a two-week decision process.
Define the minimum and maximum viable scale for your current motion explicitly.
Deal economics and minimum thresholds
What is the minimum deal value that makes the cost of acquisition worthwhile? This number is not the same as your minimum product price - it includes the time cost of the sales cycle.
An account that will generate a £5k deal after a six-month sales process is not a qualified account for a business with a mid-market ACV and a sixty-day target cycle.
A team going through this exercise might find that many accounts in their pipeline had an expected deal value well below the threshold that made the acquisition cost rational - a constraint never built into the ICP definition, which meant the ICP was passing through accounts the unit economics couldn’t support.
Step 5: Build separate ICPs for different regions and segments
A single global ICP definition almost never holds. This is because the structural signals that predict fit in one region frequently don’t predict fit in another, and the commercial and serviceability constraints are often different across markets even for the same product.
Why a single global ICP often fails across regions
A marketing technology company built its ICP as a single global definition and found it was being distorted by lumping North America and Europe together. The attributes that predicted winning in North America were different from those that predicted winning in Europe, and the combined model was accurate enough in neither. Splitting the model improved accuracy materially in both.
A second, more measurable version of this problem. A different MSP-focused security tooling vendor tracks win rate by region directly - 26% in North America, 32% in EMEA, 21% in ANZ, and the ANZ gap was unexpected enough that it’s now under active investigation.
When win rate diverges meaningfully by geography, it’s a signal that one definition is being asked to do the work of two.
Why one ICP rarely fits multiple buyer personas
If your product serves more than one distinct buyer profile - different personas, different use cases, different buying contexts - a single ICP definition is almost certainly too broad. The structural signals that predict fit for one segment don’t predict fit for another, and a definition that tries to capture both tends to be accurate for neither.
The right approach is to maintain distinct qualification criteria for each segment and be explicit about which motion you’re running and which criteria apply.
Questions to ask in this step:
Does your win rate vary significantly by region? If it does, what’s different about the regions where you win more?
Does your definition account for regional differences in commercial norms, buying cycles, or decision-making structures?
Do you have distinct buyer profiles with genuinely different structural signals? Are they being treated as one ICP or two?
Does your serviceability differ by region - language, compliance, support coverage - in ways that should change your qualification criteria?
The 5 things a complete ICP definition must answer
At the end of this process, your ICP definition should be specific enough to make targeting decisions, honest enough to exclude accounts that don’t qualify, and grounded in evidence rather than instinct.
It should answer, explicitly:
What commercial conditions make an account worth pursuing? What is the minimum deal size, and what attributes predict whether an account will reach it?
What serviceability constraints limit which accounts you can serve well, regardless of willingness to buy?
What structural and operational signals predict that the problem your product solves exists, is acute, and is the kind of problem this account is likely to spend money on?
What disqualifies an account that would otherwise pass the surface-level filters?
How does this definition vary by region, segment, or GTM motion?
Sourcing your ICP at scale
The audit is the diagnosis. It tells you what your real qualification criteria should be. The harder part - the part where most teams eventually get stuck - is applying that definition at scale.
Knowing that a company needs to have a certain operational structure, a certain type of internal team, or a certain set of revenue characteristics to qualify is useful. Being able to identify which companies in your addressable market actually meet those criteria is a different problem entirely.
Standard data providers give you firmographics. They can’t tell you whether a company genuinely owns its fleet versus outsourcing transport, or whether it has a real data-engineering function with active hiring in that area right now. They don’t give you the operational signals, structural attributes, or behavioural and compositional data that a real ICP definition, once properly built, actually requires.
In practice, this means checking a signal like that yourself involves reading job postings and team pages company by company, or building and maintaining a classification model good enough to make the same judgment call at the scale of an entire market, and then re-running it every month, since roughly 7% of any market’s qualified accounts change each month as companies grow into or out of fit.
That gap between the definition and the data is where GTM intelligence exists. Closing it takes human-level reasoning at scale, reading the signals that actually matter, the way a person would if they had time to check every company in a market by hand, rather than relying on whatever a standard provider’s database already happens to capture. And it’s why the audit, for most teams, is not the end of the process. It’s the beginning of understanding what they actually need to build.
Goodfit helps revenue leaders define, source, and grade every account in their market, so they know what to target and how to allocate resources against it.
FAQs: Auditing and rebuilding your ICP
What’s wrong with a firmographic-only ICP definition? Industry, headcount, geography, and funding stage are popular filters because they’re easy to pull from any data provider, not because they’re reliable. A list built this way tends to capture correlation rather than causation, so it ends up looking precise without actually separating buyers from non-buyers.
How do I know if an ICP filter is actually predictive? Run it against known non-buyers, not just your qualified accounts. If a similar share of your unqualified accounts would have cleared the same criteria as your qualified account list, the filter isn’t earning its place - it’s just describing who you’ve sold to after the fact rather than helping you find more of them.
What are the three layers of a complete ICP definition? Whether the deal makes financial sense, whether you can actually deliver well to that account, and whether the company’s internal setup creates a real need for what you sell. Most teams only ever build the first of these into their ICP, if any.
Why do account lists tend to grow too wide over time? Accounts usually get added on optimism and almost never get pruned once they prove out badly - there’s typically no trigger that forces a re-look once a tag is set. Across the markets Goodfit has mapped, roughly seven in ten CRM accounts sat outside a company’s actual qualified market.
Should win rate vary by region if my ICP is correct? Not by much, and a sizable gap is usually a tell. Buying committees, procurement norms, and commercial thresholds shift from one market to the next, so a model tuned for one region often distorts results in another - splitting the definition by geography tends to sharpen accuracy in both.
How often should an ICP be updated? Ideally, this is a living, breathing entity which is constantly updated. A definition built on last year’s closed deals is a snapshot of last year’s market, and given how quickly product, competition, and buyer behaviour shift, anything left untouched for more than a few quarters should be assumed stale until re-tested.
What’s the hardest part of running an ICP audit? Working out the right criteria is the more straightforward half. Finding which companies, across an entire market, actually meet those criteria is the much harder problem - standard data providers hand you firmographics, not the operational signals a real definition depends on.
How does Goodfit define, source, and grade every account in your market? Goodfit starts by defining what a genuinely qualified account looks like for your business, validated against real performance data. From there, it cleans your CRM of duplicates and dead records, sources your complete market directly, and applies human-level reasoning at scale to classify every account. Each one is then graded by expected value - the source of truth for who to target and how, so sales, marketing, and every other channel are pointed at the same accounts with the right level of attention for each.
If you’re interested in learning more about how GTM Intelligence can reinvent your GTM motions, please subscribe!